
Document Scanning
Make Scanned PDFs Searchable: OCR Settings And File Handover
The scan looks fine, but Find returns nothing. Separate the page image, OCR text layer and search index, then check the final PDF your colleague actually receives.
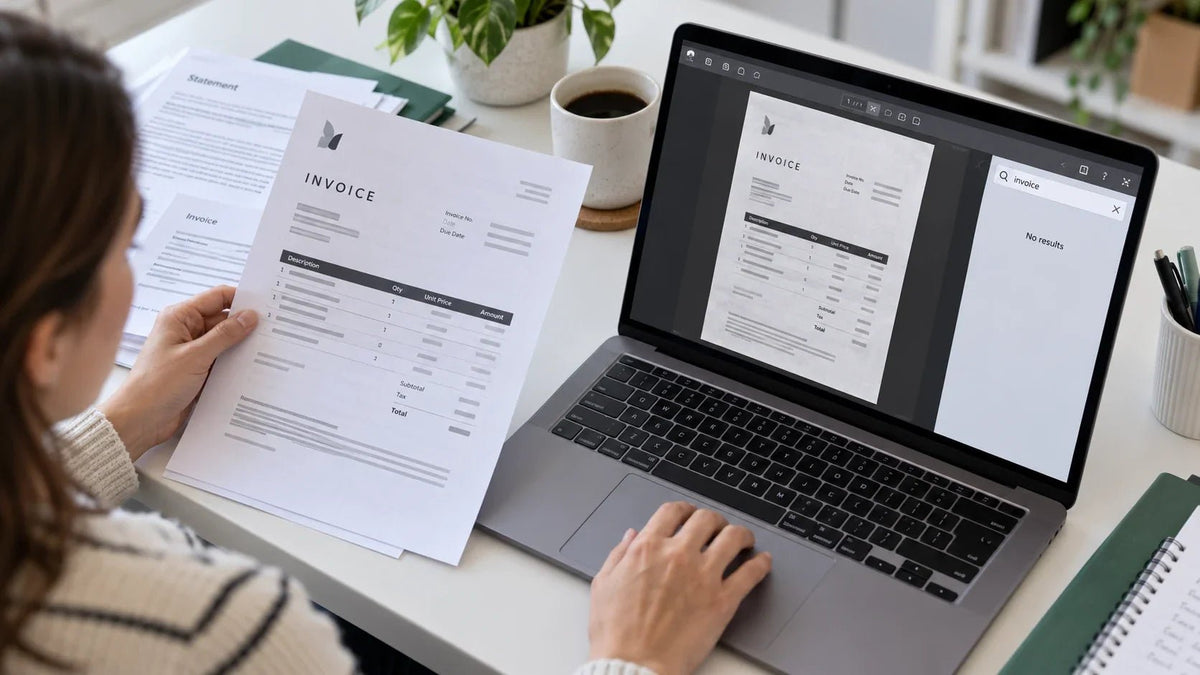
A scanned PDF needs an embedded text layer to make its printed words searchable in a PDF viewer. Check the OCR output setting, document language and final delivered file. If PDF Find works but NAS search does not, investigate indexing as a separate step.
The invoice is clearly visible. You type its reference number into Find and receive no result. A colleague opens the same file and cannot select a sentence either. The scanner may have captured the page correctly while the software saved only its image.
OCR means optical character recognition. It turns an image of text into recognised characters. That can make a document easier to retrieve, but only when the intended workflow saves those characters where the next person’s software can use them.
Test The Final PDF Outside The Scanning Application
Open the file your colleague would actually receive, using a PDF viewer’s own Find command. Search for a distinctive printed word, then try selecting and copying a short sentence. Check more than the first page of a multipage document.
Selecting a whole image is not the same as selecting its words. Likewise, finding the filename or a manually added title does not establish that the body text is searchable.
| Result | Likely Next Check |
|---|---|
| No words can be selected or found | Whether OCR ran and embedded text in this PDF output. |
| Some words work; small or skewed text fails | Capture quality, language and OCR recognition limits. |
| Scanning app finds words; shared PDF does not | Catalogue-only text, export settings or a different delivered file. |
| PDF Find works; NAS search does not | Indexed folder, file/content support, permissions and indexing progress. |
Keep this test small: one ordinary page, one dense table and one page with the languages used in the real workload. A successful sample is more useful than converting an entire archive before checking the output.
Separate The Page Image, Text Layer And Search Index
The visible scan. It can look clear without containing searchable characters.
Recognised words saved inside the PDF for compatible viewers to find and copy.
A separate catalogue used by a computer, NAS or document system to locate files and supported content.
Those functions are related, but they are not interchangeable. A NAS search service does not automatically perform OCR on every image-only PDF. A scanning application’s internal search can also succeed without proving that a portable text layer is present in the exported file.
Check The Scan Job’s PDF And OCR Settings
Start with the output profile used for the affected batch. Look for the application’s searchable-PDF or text-recognition option, the selected language and the destination. Saving with a .pdf filename alone does not enable OCR.
In PaperStream Capture, searchable-PDF creation is configured in the scan/output settings, including the document language. Review the job that was actually used rather than another profile with a similar name.
ScanSnap Home provides searchable-PDF workflows too. Its catalogue can hold recognised text separately from the text embedded in the file. If a document is searchable only inside Home, inspect the PDF output option and verify a copy in another viewer.
The exact controls depend on the supported software version and scan route. Confirm the workflow for the installed application before changing a shared production profile.
Give OCR A Readable Page
OCR cannot reliably interpret detail that the scan did not capture. Small type, skew, faint originals, heavy compression and complex layouts can reduce recognition quality. Handwriting also needs a suitable recognition capability; ordinary printed-text OCR is not a promise of accurate handwriting extraction.

For typical office print, 300 dpi is a practical starting point for a sample test, rather than a universal requirement. Compare the result with the workload’s file size and processing time. More resolution does not correct a folded page, the wrong language or an unsuitable recognition engine.
Set the appropriate language or supported language combination. Check critical references and amounts manually, especially where O and 0, or I and 1, could be confused. Searchable text is useful assistance, not verified business data.
Missing or overlapping pages need a capture fix first. The scanner double-feed guide explains paper preparation and feed checks before OCR is expected to work on the batch.
Check Processing Completion And The Destination Route
A feeder finishing its last sheet does not necessarily mean all recognition and file-saving work has completed. Check the application’s processing status and confirm that you are opening the finished output, rather than an earlier copy.
Direct-to-network, cloud and computer-based scan routes may have different OCR capabilities or restrictions. Do not assume the same result merely because they originate from the same scanner. Test the exact destination and settings used by the team.
Then check the handover. A later export, flattening operation or particular print-to-PDF route can change what the final file contains. Compare the original searchable output with the actual file sent, downloaded or uploaded. Avoid blaming every PDF printing tool without testing its result.
Recover An Existing Archive Without Rescanning Everything
If the page images are readable, suitable OCR software may add searchable text to existing files. ScanSnap Home also supports later conversion for supported documents created through its workflow. Do not assume that an application accepts every external, protected or unusually formatted PDF.
Preserve the original and process a copy. Test a small representative folder, including multipage documents, before starting a large job. Verify page count, orientation, search results and any file-size change.
Keep files in an approved processing environment for the documents involved. A confidential invoice archive should not be uploaded to an unapproved web converter merely because it is convenient.
Rescanning becomes useful where the original capture is incomplete or unreadable. If the image is sound and only the text layer is missing, correcting the software step may be enough.
When PDF Search Works But Storage Search Does Not
Once the PDF’s own Find command works, check the storage search service separately. Is the destination folder indexed? Is PDF content supported and enabled for that service? Has the index finished updating, and can the searching user access the file?
Synology Universal Search supports indexing of supported documents and locations, but configuration and access scope still matter. Moving a PDF to a NAS is not proof that every search interface will immediately search its contents.
A document management system adds further functions such as workflow, permissions and retention. It should be selected for those needs. Neither a searchable PDF nor a shared folder automatically supplies a complete approval or records-management process.
Choose Scanner Hardware For The Capture Work
A new scanner is justified by the paper workload: feeding reliability, batch size, document types and daily handling. It should not be the first purchase made simply because an OCR checkbox was missed.

The Ricoh fi-8170 is a workgroup scanner option to assess against that workload. Compare the complete software and destination workflow alongside the scanner range, rather than treating the hardware model as a guarantee of every OCR or document-management feature.
Make The Delivered File The Acceptance Test
A working result is straightforward: the final recipient can open the PDF, find a known word and inspect the correct pages. If central search is required, the approved user must also be able to retrieve it through the intended storage system.
Keep the scanner model, application version, profile, language and destination with a representative sample. Fix the first failing stage, then repeat the same test. That makes the choice between a settings correction, OCR processing and a hardware upgrade much clearer.
Frequently Asked Questions
Why can I see words in a PDF but cannot search them?
The page may be stored as an image without an embedded text layer. Optical character recognition, or OCR, interprets the image and can add searchable text. Test the final PDF with its own Find function and by selecting a known word.
Is a searchable PDF the same as a Word document?
No. A searchable PDF can preserve the scanned page image with a text layer for finding and copying words. It does not necessarily provide a clean, editable document layout or verified data extraction.
Do I need a new scanner to create searchable PDFs?
Often the missing step is in the scanning application or output profile. Check whether the existing supported software can create a searchable PDF, then test a representative batch before deciding that hardware is the limitation.
Can already-scanned PDFs be made searchable?
Suitable OCR software can process many existing image-based PDFs. Support depends on the application, file type and restrictions. ScanSnap Home also has a later-conversion workflow for supported ScanSnap documents. Preserve the original and test a copy first.
Why can ScanSnap Home find a word but my colleague cannot?
The application may hold recognised text in its own catalogue while the delivered PDF lacks embedded text. Enable the appropriate searchable-PDF output and test a copy opened outside the scanning application.
Why does PDF Find work but NAS search cannot find the file?
Check the NAS’s indexed folders, supported file types, content-search settings, permissions and indexing progress. Working OCR inside the PDF and a completed storage search index are separate requirements.


